Technology has various trajectories that draw out in long arcs that overlap and stack on top of one another. One arc I have been giving considerable thought to is the proliferation of data and how accessible it has become. A large motivator of gaining my master’s in data science (after my bachelors in art, of course) was the insatiable desire to understand things.
This itch intensified as the vision of cloud computing was being evangelized and digital transformation was coined as both term and consultative offering. My gut knew that data was on the verge of becoming a market mover and I wanted to follow the understanding beyond what search queries and qual surveys could give.
Data lived in a variety of dispersed places and formats while access to them ran on networking that required a minimum of eighteen clicks. With the evolution of connectivity speeds and the reimagining of foundational infrastructure, a door for data velocity was swung open.
KPMG Ignition’s recent Me in Mind, and its framing of scarcity, surplus, and saturation captures the data arc I continually come back to incredibly well: both businesses and people have moved from not having enough data to having to navigate an excess of information, options, and opinions. This movement from data scarcity to data surplus has led many of us into prosperous digital marketing careers and transformed ad tech.
And now we are saturated in data.
Saturation is a richness, a fullness of max capacity. You can only work downwards, not up, from saturation. The more you attempt to add, the more you muddy and dull things, reducing the purity of it. We continue to sell creative, strategy, social and content using auspicious headlines: break the algorithm, steal share of attention, become memorable and unignorable. These bullish lines can be provocative in any sound sales pitch, but they are sneakily oriented around a premise of scarcity, not of saturation.
An audience drowning in content that needs to be rescued from doomscrolling is a far easier pitch than acknowledging the evidence of audiences actively and habitually avoiding information. Information overload is something that passively happens to people while avoidance is something they actively do. If people were simply overloaded, a louder message could eventually break through, but people practicing avoidance have already, and intently, decided what they will let in.
I recently wrote The Intermediary Always Wins, which touches on how reliance on a third party and parasocial relationships guide decisions. One reason for this is because one trusted voice or opinion can assuage a person’s belief that they have given adequate effort and attempted research to make a good enough decision. Whether the intermediary is AI chat, an influencer, Google summary, or the first product review that has a semi-focused photo, we see the people actively reducing the amount of information they confront in ways that relieve the strain of making a choice.
Companies are just as saturated and struggling to find purchase on what matters at a decision point, though their way of coping can look like the opposite of avoidance. It is incredibly common for clients and teams to ask for more data, believing volume will bring them closer to an audience, an answer or a decision, when we already have more than we can meaningfully interpret. More rarely changes or magically reveals anything, as the tendency is to ask the same questions, or let prejudice and anecdotal experience take over, and then mistake the consistency of the answers for understanding. We find confidence in reassurances while fearing anything unknown.
Humans are already predisposed to spot patterns, even if they don’t exist, but knowing what is actively missing is a different skill. One of my professors drilled into us that the first thing you should do with data is “see the shape of it”, which he literally meant we had to visualize the data before anything else. Francis Anscombe made the same case in 1973 showing how four datasets that had nearly identical means, variances, correlations and regression lines looked nothing alike once visually plotted. AI summaries similarly sit closer to the summary statistics than to the plot. They prevent us from seeing the actual shape of the information—and whatever is missing from it.
When you see enough data shapes, you can become adept at noticing the negative space. The data will be attempting to tell you something, but as most data scientists know, you don’t trust data, you let it guide you. The negative space is where you hypothesize, try things, muck around. It is where you can uncover multiple truths and where alternative explanations live. In the same way the absence of color in the FedEx logo reveals the forward arrow, absence can reveal direction.
Playing in the negative space is about looking at all of the data, the full shape before any summary, statistical or otherwise, because what’s missing only becomes visible once you’ve seen what’s there. It means to pay attention to what was suppressed as an outlier, or a segment that may have been deemed too small, to ask questions the data does not directly answer, to analyze how a belief stated does not match the behavior observed, and to notice the absence of a pattern where one should be.
The negative space is not empty at all, if you are willing to look beyond averages. We do not need more data to find insights, but to be better at interpreting the data already held and willing to interrogate the gaps in a relentless pursuit of curiosity and understanding. In a saturated market there is no adding your way up, and the negative space is the one place left with room to move and find what is interesting.
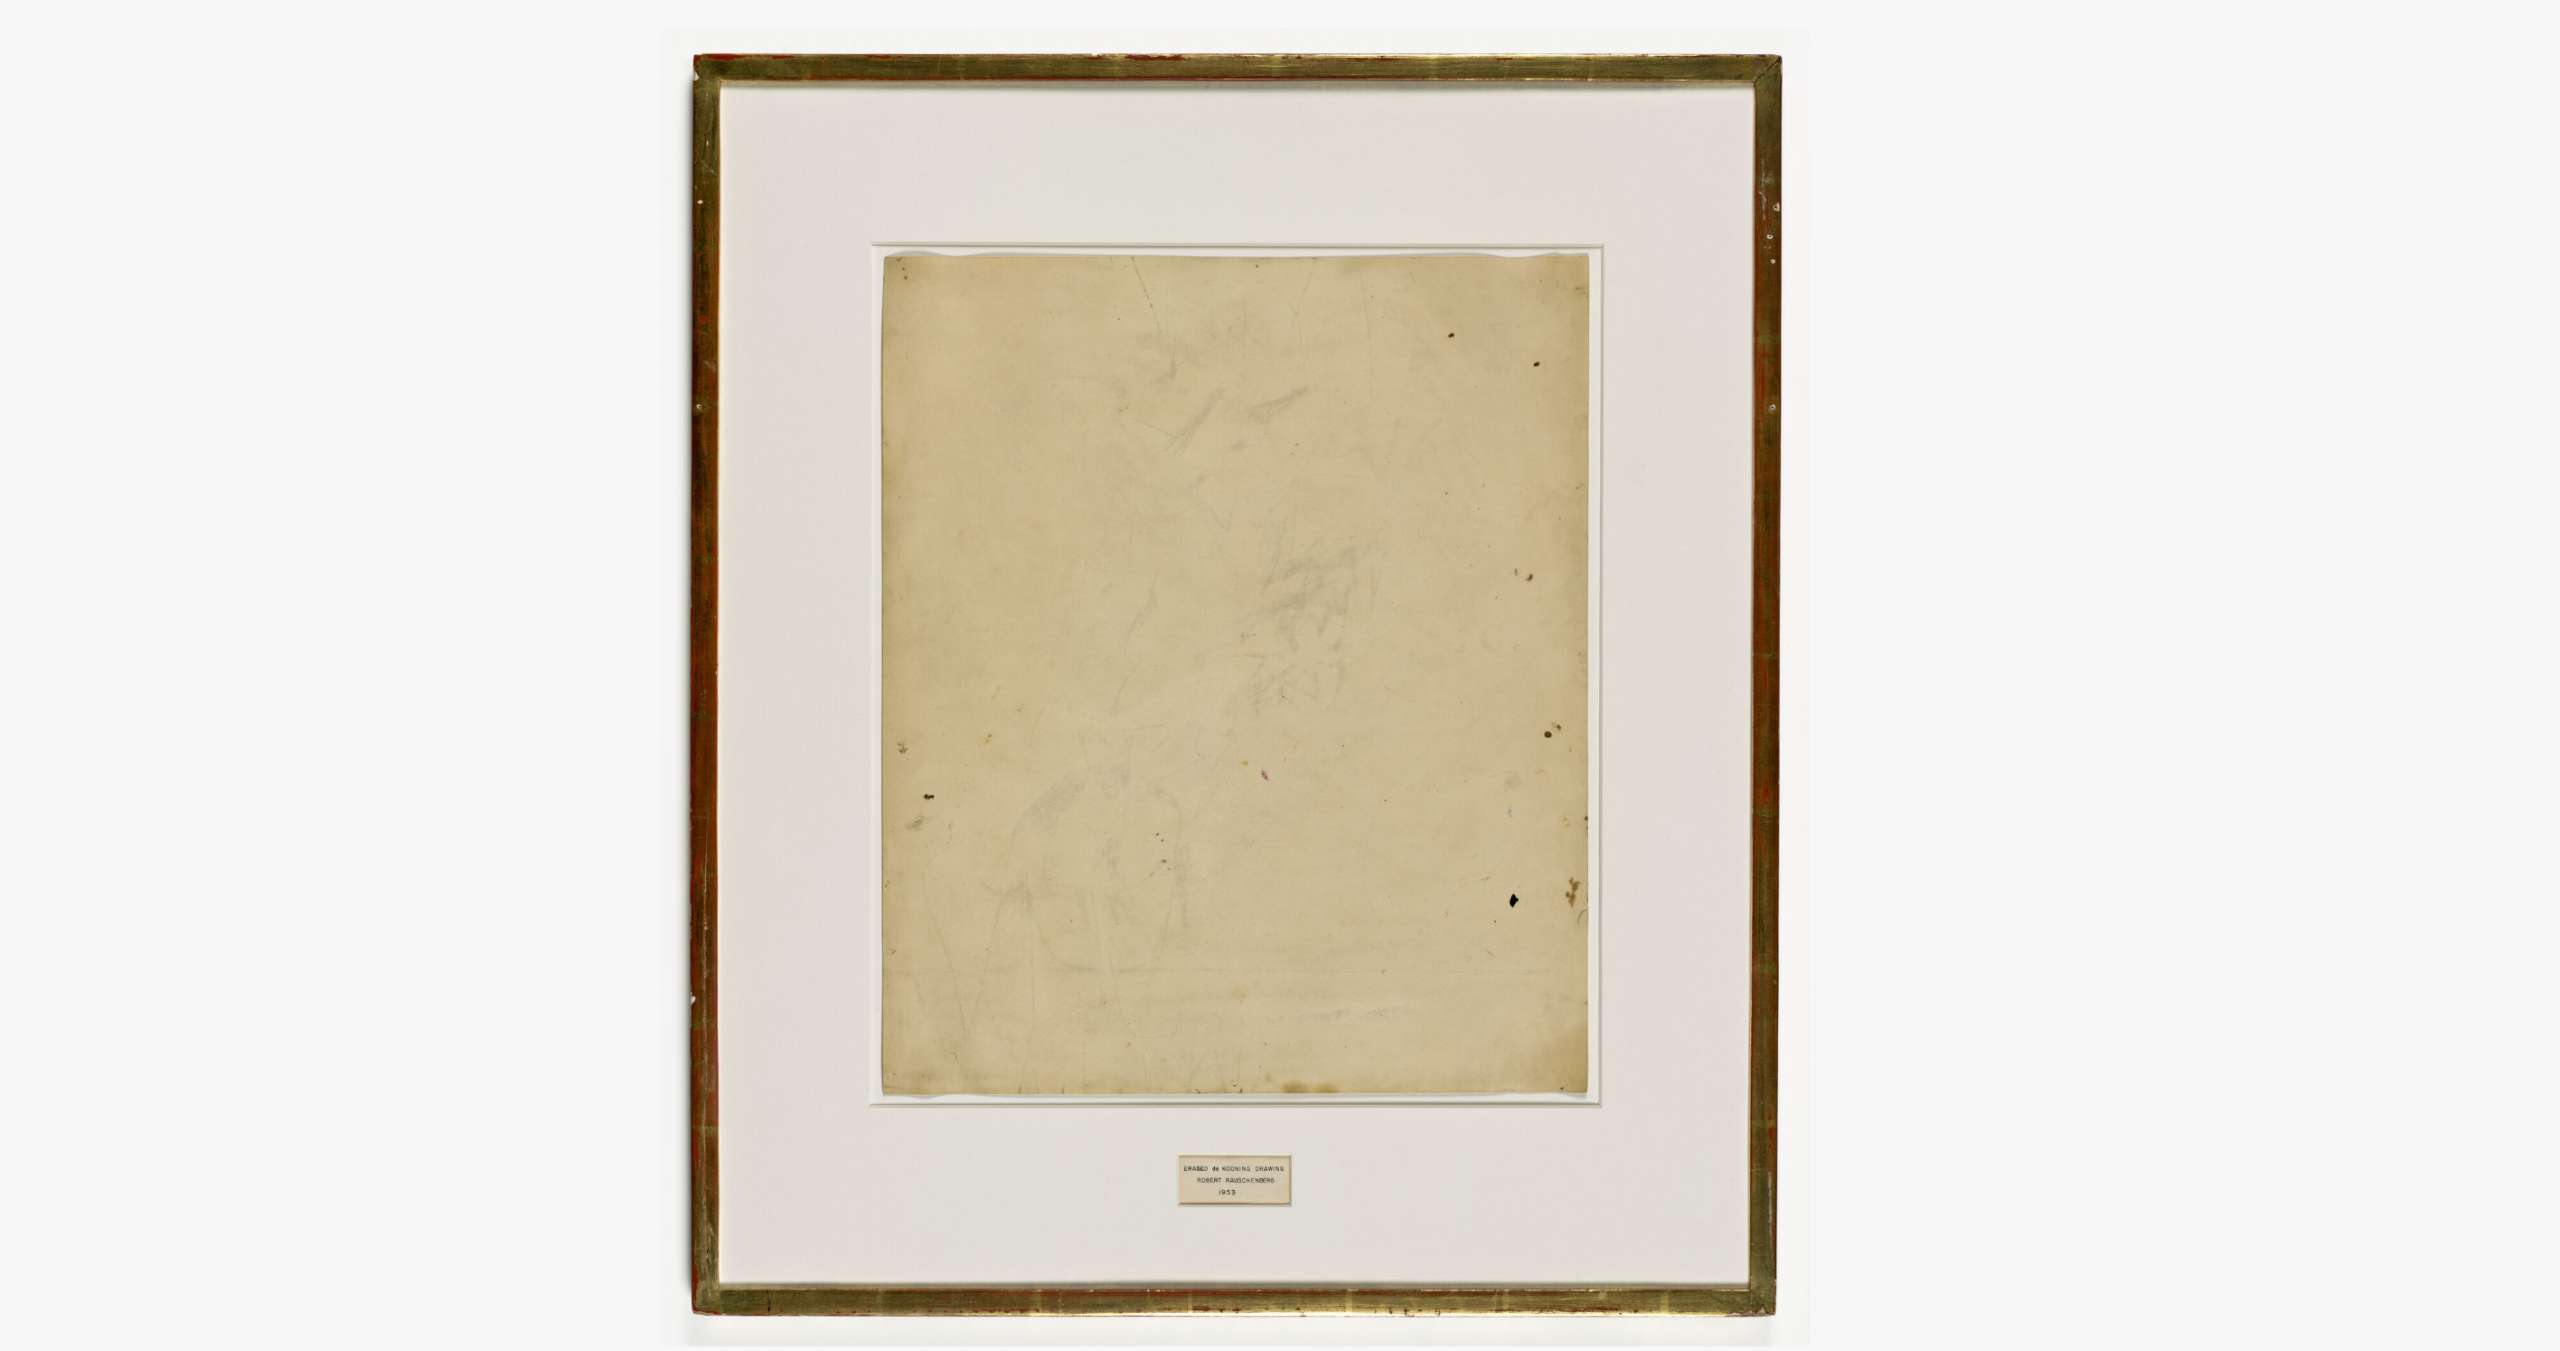
(the art purposely featured for this post is Robert Rauschenberg, Erased de Kooning Drawing)